Dollar per Image Bench

    You can pay 7.5× more for a worse image.

    We sent the same prompts to 7 frontier image models through one API and had two vision LLMs grade every result. Plotted on a cost × quality map, the most expensive model lands below the cheapest. Hover any point.

    ← All research
    7.5×
    price spread
    7.7×
    $ / quality-pt
    9.1×
    latency spread
    +1.0
    judge gap
    Cost × quality map
    price per image (log scale) vs. judged quality
    OpenAIGoogle
    BEST VALUEOVERPAYING4.04.55.0$0.0080$0.020$0.030$0.040$0.060cost per image (USD, log scale →)quality (1–5)+7.5× price, lower qualityGPT-Image-1 Minicheapest · winsGPT-Image-2Imagen 4 FastGPT-Image-1.5GPT-Image-1Imagen 3Imagen 4 Ultrapriciest · loses

    x-axis is logarithmic. Quality = mean of a two-judge vision ensemble (Claude Opus 4.7 + GPT-5.5), 1 to 5. Bubble outline marks model family.

    // the proof

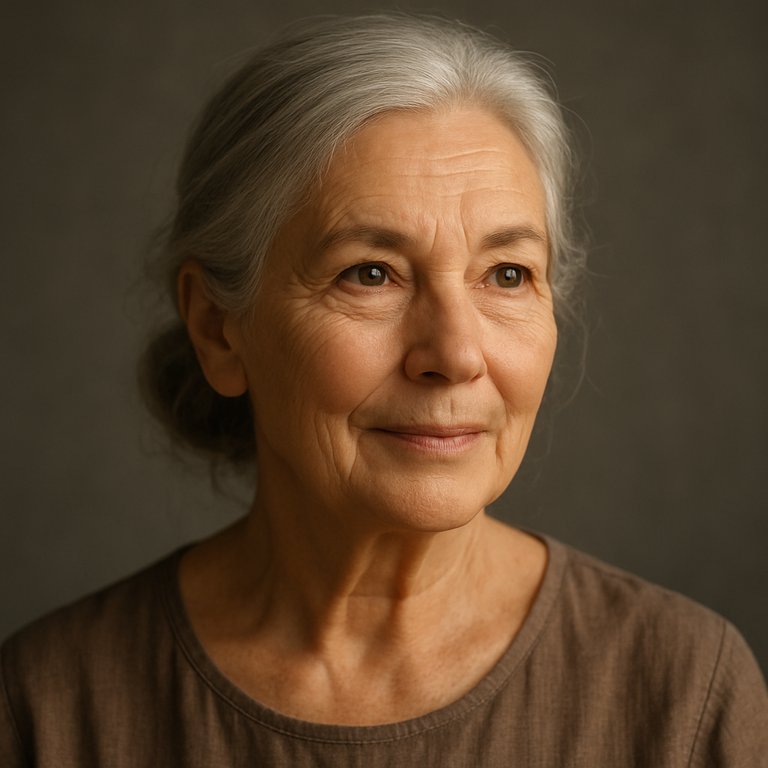
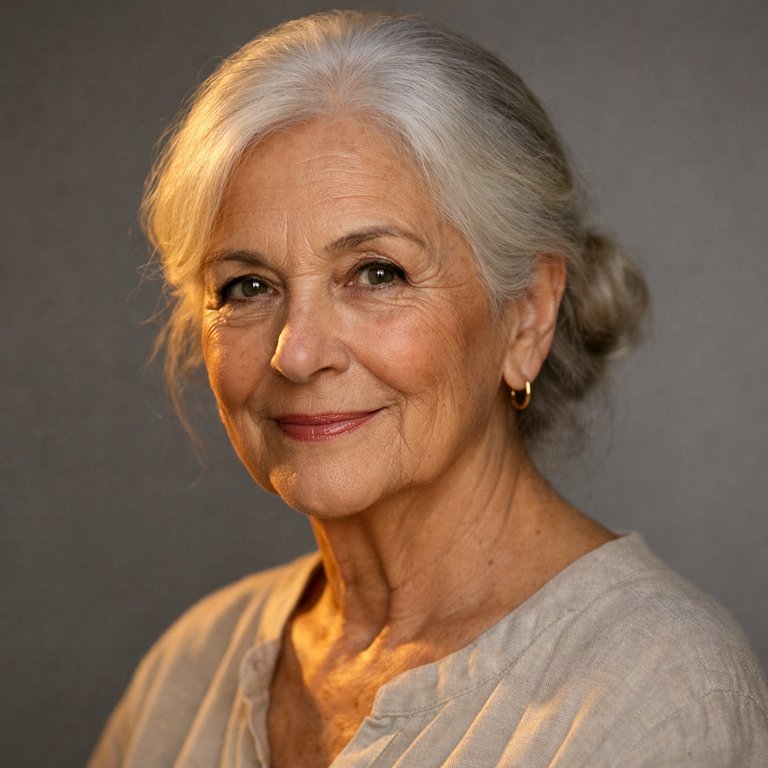
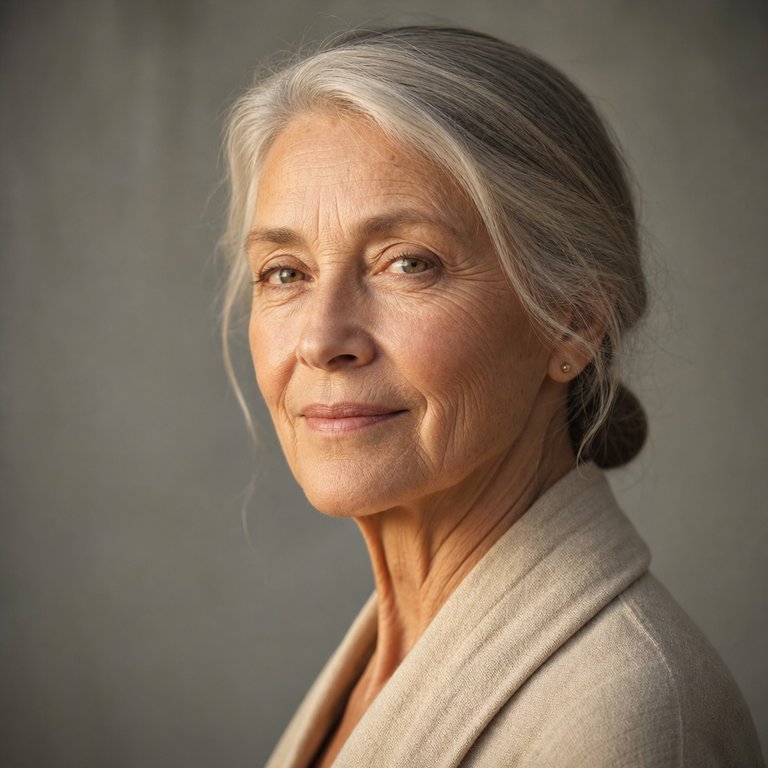
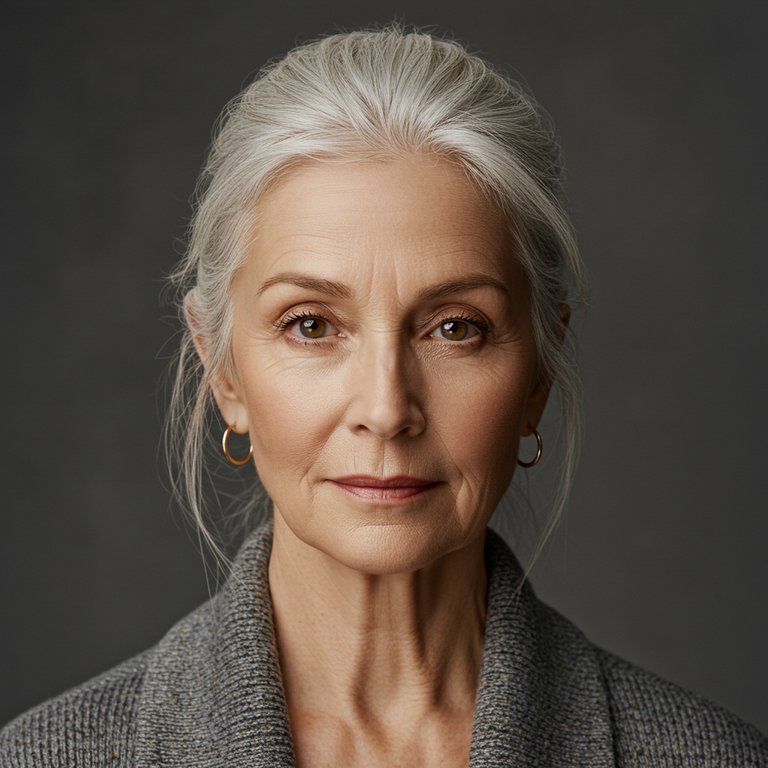
    Can you tell which one cost 7.5× more?

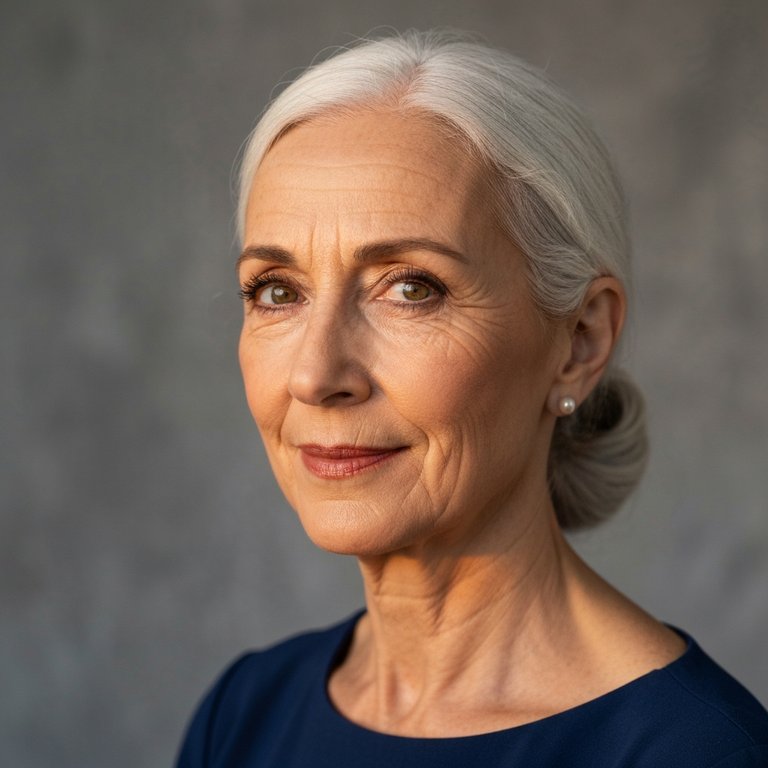
    Every image below is the same prompt, rendered by a different model, from $0.0080 to $0.060 each. Look first. Then reveal the prices.
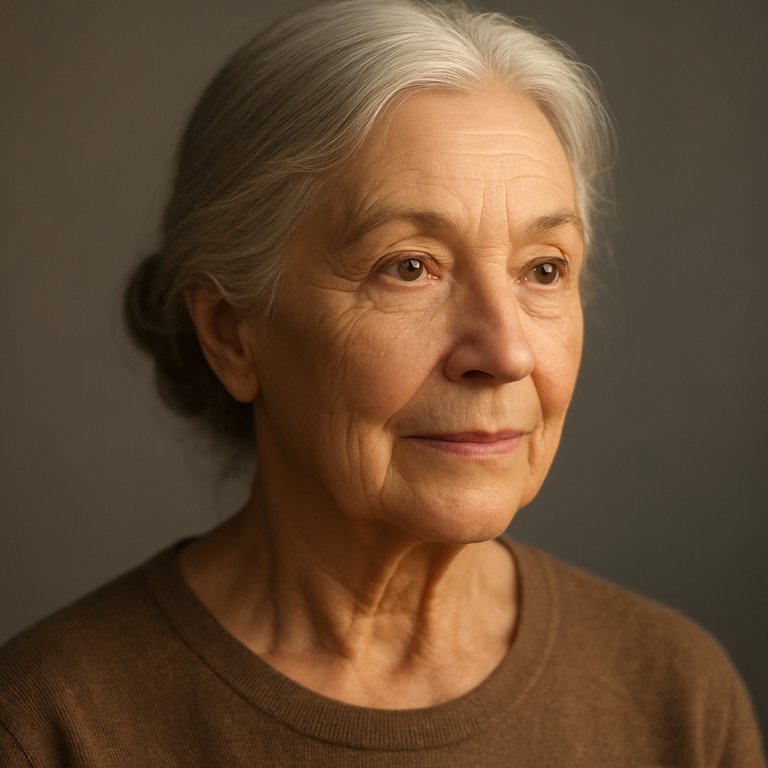
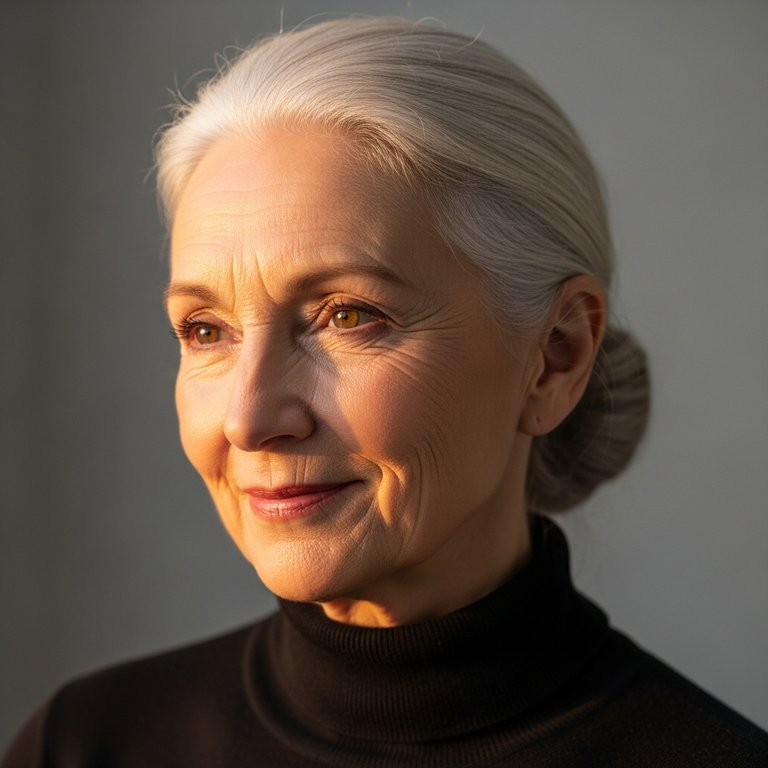
    prompt: "A photorealistic portrait of a 70-year-old woman with silver hair tied in a low bun, warm hazel eyes with visible crows feet, soft golden hour light from camera left, shallow depth of field, 85mm lens, neutral gray backdrop."
    GPT-Image-1 (legacy OpenAI)
    $0.040
    quality 4.17 / 5
    GPT-Image-1 (legacy OpenAI)
    PRICIESTImagen 4 Ultra
    $0.060
    quality 4.05 / 5
    Imagen 4 Ultra
    CHEAPESTGPT-Image-1 Mini
    $0.0080
    quality 4.16 / 5
    GPT-Image-1 Mini
    GPT-Image-1.5
    $0.032
    quality 4.32 / 5
    GPT-Image-1.5
    GPT-Image-2
    $0.019
    quality 4.92 / 5
    GPT-Image-2
    Imagen 3 (legacy Google)
    $0.040
    quality 3.87 / 5
    Imagen 3 (legacy Google)
    Imagen 4 Fast
    $0.020
    quality 3.98 / 5
    Imagen 4 Fast
    The cheapest render (GPT-Image-1 Mini, $0.0080, quality 4.16) scored higher than the priciest (Imagen 4 Ultra, $0.060, quality 4.05) at 1/7.5th the price.
    // the waste

    Dollars spent per point of quality

    Normalize price by the quality it actually buys and the gap is stark: the priciest tier burns 7.7× more money for each unit of measured quality.

    GPT-Image-1 Mini
    $0.0080/img
    $0.0154
    GPT-Image-2
    $0.019/img
    $0.0335
    Imagen 4 Fast
    $0.020/img
    $0.0402
    GPT-Image-1.5
    $0.032/img
    $0.0592
    GPT-Image-1
    $0.040/img
    $0.0767
    Imagen 3
    $0.040/img
    $0.0826
    Imagen 4 Ultra
    $0.060/img
    $0.1184
    // the hidden tax

    What the price card doesn't show

    Sticker price is the easy number. The taxes that actually hit a product live in latency, retries, and who's doing the grading.

    88%
    retry rate

    GPT-Image-2 tops raw quality (4.92) but 88% of calls retried and 38% errored, and it makes you wait 66.3s.

    9.1×
    latency spread

    From 7.3s (Imagen 4 Fast) to 66.3s (GPT-Image-2). Same task, 9.1× the wait. The difference between interactive and "come back later."

    +1.0
    judge disagreement

    GPT-5.5 scored every model higher than Claude did, by up to 1.0 points (on Imagen 4 Fast). Why we report both judges, never one.

    Method. Each model rendered an identical prompt set routed through one API. Quality is the mean of a two-judge vision ensemble (Claude Opus 4.7, the stricter judge, + GPT-5.5) on a 1 to 5 scale. Cost is read from a static pricing table dated 2026-05-20. Image APIs return no usage metadata. Latency is end-to-end wall-clock (p50). This is the Pilot · n=8 · 2026-05-24 (total spend $1.27); numbers reflect the current pilot_combined_results.json and differ from the README's earlier routine-only subset. Figures are pilot-scale and directional, not a final leaderboard.

    dollar-per-image-bench · generated by make_visualization.pyRaushan Sharma· repo·MIT

    Asia's largestsovereign AI gateway.

    1,000+ AI models. One endpoint. Your data stays inside your border.

    Get an API key